Ongoing projects
1) Medical image analysis
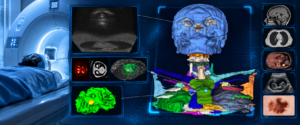
Medical imaging plays a central role in the diagnosis, treatment planning, and monitoring of diseases. Advances in artificial intelligence are creating new opportunities to extract accurate and clinically relevant information from increasingly complex medical images. At LARIVIA, our research focuses on developing advanced deep learning methods for medical image classification and segmentation across multiple imaging modalities, including MRI, CT, ultrasound, PET, X-ray, and dermoscopic imaging.
Our models aim to automatically identify and delineate anatomical structures, lesions, tumors, and other pathological regions while addressing challenges such as limited annotations, variability across patients and imaging systems, and the need for robust generalization. By combining deep learning, foundation models, multimodal learning, and efficient segmentation techniques, our research seeks to improve diagnostic accuracy, support personalized treatment and disease monitoring, and advance the development of reliable and intelligent computer-assisted healthcare systems.
2) UAV imagery for intelligent transportation systems
This research explores the use of artificial intelligence (AI) and augmented reality (AR) technologies for efficient guidance of unmanned aerial vehicles (UAV) in various contexts of intelligent transportation systems such as delivery, infrastructure inspection and surveillance. The project has two major thrusts:
a) UAV-based infrastructure inspection
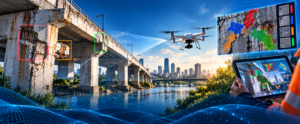
Concrete infrastructure, including bridges, overpasses, and roads, is essential to modern urban environments and requires systematic inspection to ensure long-term safety, reliability, and durability. This research focuses on developing advanced deep learning and computer vision models for automated infrastructure inspection. Our methods enable the classification, detection, and segmentation of structural defects such as cracks, spalling, corrosion, and exposed reinforcement. By leveraging drone imagery and intelligent visual analysis, the project aims to support accurate, efficient, and scalable assessment of bridges and other critical infrastructure.
Watch demo video built in collaboration with the National Research Council Canda:
b) Safe landing zones detection for autonomous drone navigation.
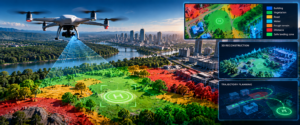
As Unmanned Aerial Vehicles (UAVs) are increasingly deployed in civilian applications, safe and autonomous navigation has become a critical challenge, particularly in complex urban and natural environments. This research focuses on developing deep learning and computer vision methods for automatic safe landing zone (SLZ) identification using passive vision sensors. Our models analyze drone imagery to understand terrain characteristics and map them into different levels of landing safety. Combined with semantic segmentation, 3D scene understanding, and dynamic environment analysis, these methods support reliable landing decisions in both routine and emergency situations, while also providing valuable information for autonomous UAV navigation and trajectory planning.
c) Smart eyes in the sky: AI for disaster response
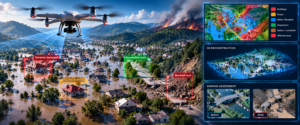
Natural disasters can rapidly affect large and often inaccessible areas, making timely and accurate situational awareness essential for effective prevention, response, and recovery. This research focuses on developing advanced computer vision and AI methods for analyzing aerial images and videos captured by drones in disaster-affected environments. Our models extract critical information from high-resolution imagery to identify hazards, map vulnerable areas, assess infrastructure conditions, and monitor environmental changes. During and after disasters, these technologies enable rapid damage assessment, localization of affected or inaccessible areas, and analysis of evolving conditions. By combining drone-based sensing, deep learning, and intelligent scene understanding, the project aims to provide actionable information for faster and more informed emergency response and disaster management.
3) Mutimedia analysis for cybersecurity
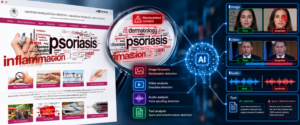
The rapid growth of digital multimedia has created new cybersecurity challenges, including deepfakes, misinformation, spam, and maliciously manipulated content. Detecting these threats requires intelligent methods capable of jointly understanding visual, textual, audio, and temporal information.
At LARIVIA, this research focuses on developing advanced AI and machine learning methods for the representation, analysis, and authentication of multimedia content. Our work addresses deepfake detection and attribution, spam and misinformation detection, and multimedia integrity across images, videos, text, and audio. We explore deep learning, vision-language models, Large Language Models (LLMs), and multimodal learning, together with self-supervised, unsupervised, adversarial, and metric learning. By combining complementary modalities and domain knowledge, our research aims to develop robust and generalizable multimedia forensics technologies capable of detecting emerging and previously unseen forms of digital manipulation and cyber threats.
Past projects
1) Semantic image/video segmentation
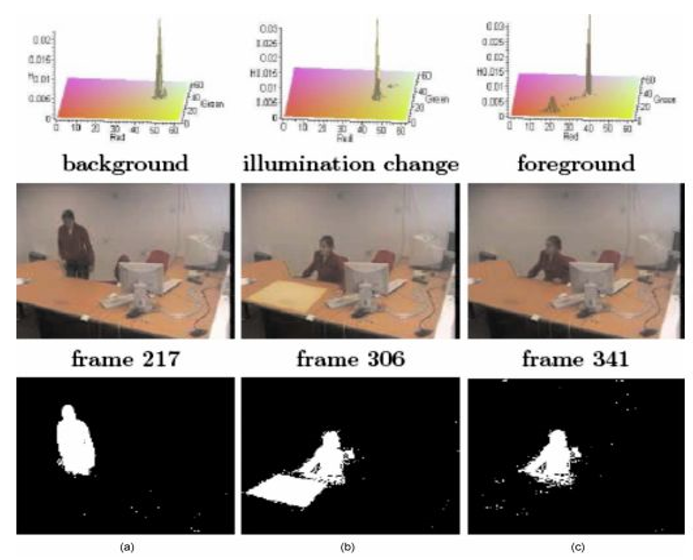
Image and video object segmentation are important problems for visual image and video understanding. This project aimed at developed robust statistical approaches based on heavy-tailed distributions for color and texture representation and segmentation. These statistical models enhanced the resilience of segmentation to outlying data such as noise and spurious foreground and background artefacts, which enhanced the accuracy of object segmentation. Several applications have also been developped, such as image and video foreground segmentation, and object tracking.
2) Image/video activity recognition
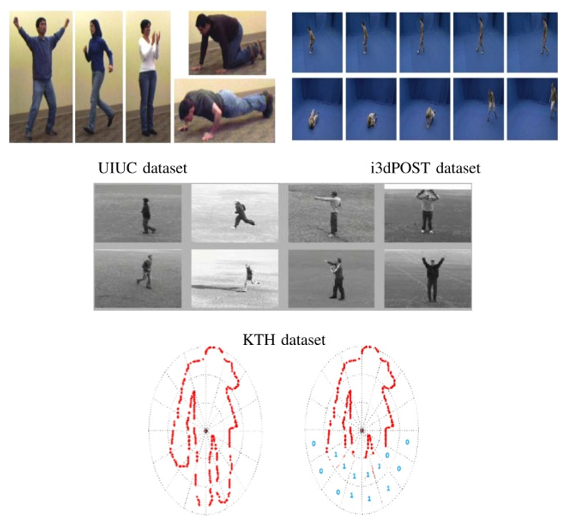
The LARIVIA laboratory previously proposed advanced statistical models based on multinomial kernel logistic regression for activity recognition in images and videos. This innovative approach significantly advanced the field of computer vision and machine learning, enabling more accurate and nuanced understanding of complex activities depicted in visual media. By integrating multinomial logistic regression with kernel methods, these models enhanced the ability to interpret and classify diverse activities invilving inter-person interactions, a crucial step forward for applications requiring detailed visual analysis and recognition.
3) Texture modeling and applications
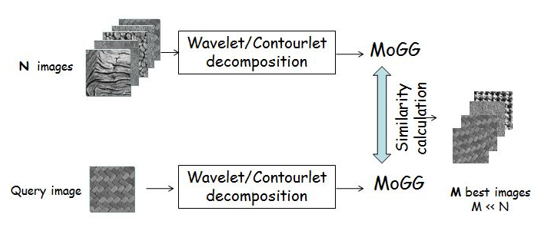
The LARIVIA laboratory previously undertook a research project focused on creating a robust statistical model using the mixture of generalized Gaussians (MoGG) formalism. This model was specifically designed for texture modeling, with a strong emphasis on applications in content-based texture retrieval and defect detection in fabric images. Utilizing the MoGG approach, the laboratory significantly advanced the capabilities of texture analysis, marking a notable achievement in the realms of computer vision and artificial intelligence.